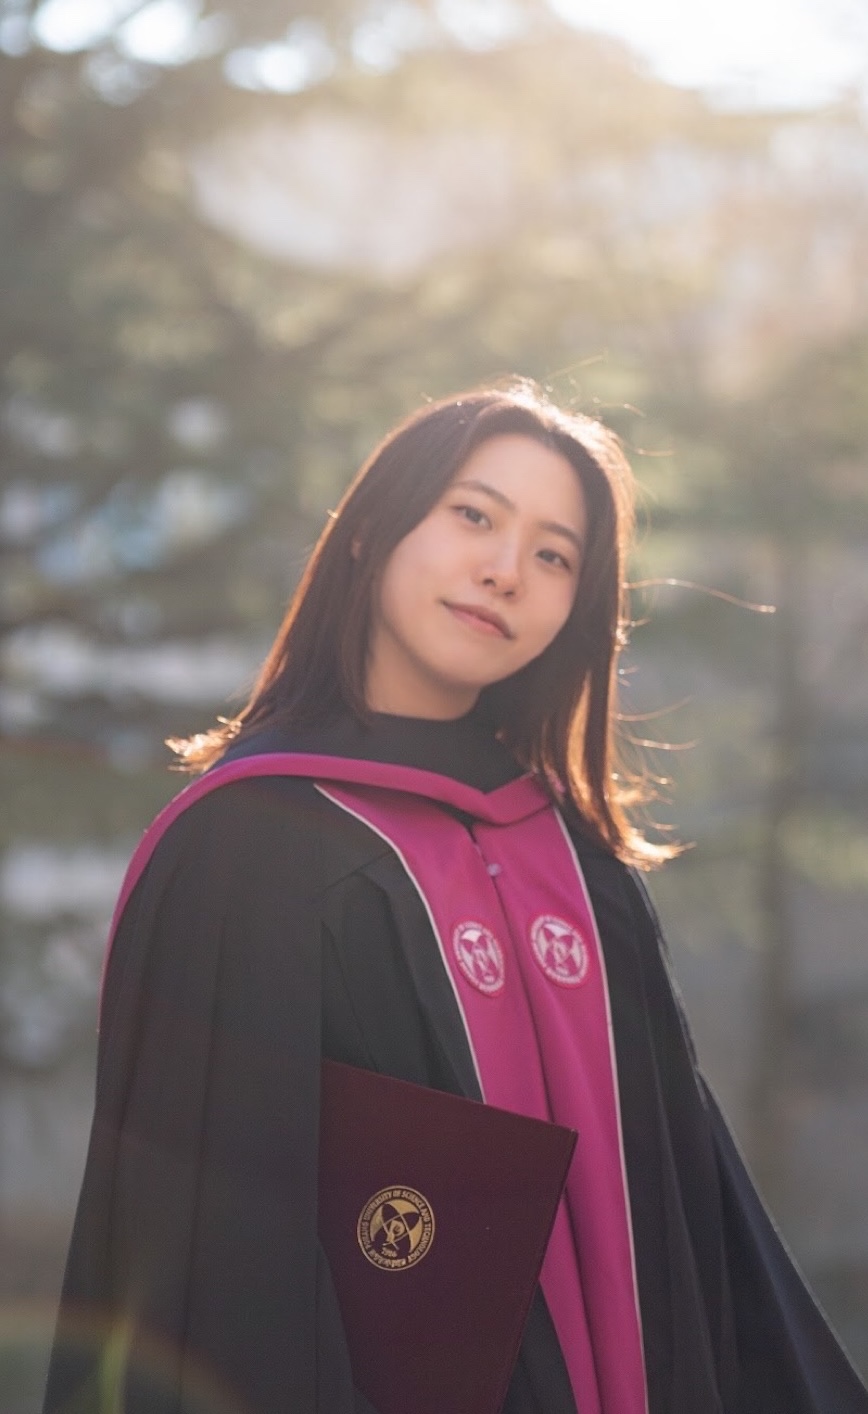
I am currently working at Markr AI. My research interests include language modeling and model alignment, with a particular focus on safety and multimodal learning.
Striking a balance between helpfulness and safety remains a fundamental challenge in aligning large language models. To achieve this balance, models should refuse harmful queries (e.g., "How do I shoot someone?") while remaining responsive to benign inputs, even those superficially resembling harmful queries (e.g., "Where can I shoot a good photo?"). However, models often struggle to distinguish genuinely harmful queries from benign queries that contain superficially risky language, resulting in false refusals. In this paper, we address the issue by decomposing a response in the safety-tuning dataset into two distinct components: (i) a boilerplate refusal statement and (ii) a rationale explaining the refusal. Our experiments and analyses show that refusal statements impede accurate discrimination between harmful and benign queries by inducing reliance on superficial cues. In contrast, training solely on rationales reduces false refusals while maintaining a comparable level of safety performance. Rationale-Only benefits also appear in our ICL configuration and remain compatible with the evaluated inference-time mitigation methods. The results emphasize the necessity of precisely curated, fine-grained safety supervision datasets and outline directions for constructing aligned agents that better reconcile helpfulness with safety.
@inproceedings{kim2026refuse,title={Refuse without Refusal: A Structural Analysis of Safety-Tuning Responses for Reducing False Refusals in Language Models},author={Kim, Minji and Kim, Hyounghun},booktitle={Proceedings of the 2026 Conference on Empirical Methods in Natural Language Processing (EMNLP)},year={2026},eprint={2609.04714},archiveprefix={arXiv},primaryclass={cs.CL},url={https://arxiv.org/abs/2609.04714},doi={10.48550/arXiv.2609.04714},}
Knowing What Not to Answer: Selective Non-Compliance in Vision-Language Models
Minji Kim, Jihyoung Jang, and Hyounghun Kim
In Proceedings of the 2026 Conference on Empirical Methods in Natural Language Processing (EMNLP), 2026
Vision-language models (VLMs) are expected to respond helpfully to appropriate requests while withholding compliance with requests that are incorrect, unsafe, infeasible, or unanswerable. However, existing benchmarks predominantly evaluate non-compliance at the level of the query as a whole, assuming that each request either warrants compliance or requires withholding compliance. In practice, real-world queries can contain a mixture of answerable content and components for which compliance should be withheld. In this paper, we introduce KoNA, a benchmark for evaluating selective non-compliance in VLMs across five categories: False Premise, Visual Inaccessibility, Universal Unknown, Task Feasibility, and Safety. Each task evaluates two capabilities: query-level non-compliance and component-level non-compliance under paired single and compound queries. Our evaluation across diverse VLMs shows that models often fail to refuse, correct, or abstain appropriately, and these failures become more pronounced when queries require selective non-compliance. To address this challenge, we fine-tune VLMs using KoNA examples that require selective non-compliance, together with a fully answerable set that should receive direct answers. Our fine-tuned models achieve substantial improvements in non-compliance accuracy while largely maintaining performance on fully answerable tasks. These results suggest that the fine-tuned models can distinguish between answerable components and those requiring non-compliance and respond in a task-appropriate manner.
@inproceedings{kim2026knowing,title={Knowing What Not to Answer: Selective Non-Compliance in Vision-Language Models},author={Kim, Minji and Jang, Jihyoung and Kim, Hyounghun},booktitle={Proceedings of the 2026 Conference on Empirical Methods in Natural Language Processing (EMNLP)},year={2026},eprint={2609.04720},archiveprefix={arXiv},primaryclass={cs.CL},url={https://arxiv.org/abs/2609.04720},doi={10.48550/arXiv.2609.04720},}
Revealing the Inherent Instructability of Pre-Trained Language Models
Seokhyun An, Minji Kim, and Hyounghun Kim
In Findings of the Association for Computational Linguistics: EMNLP 2025, 2025
Instruction tuning – supervised fine-tuning using instruction-response pairs – is a key step in making pre-trained large language models (LLMs) instructable. Meanwhile, LLMs perform multitask learning during their pre-training, acquiring extensive knowledge and capabilities. We hypothesize that the pre-training stage can enable them to develop the ability to comprehend and address instructions. To verify this, we propose Response Tuning (RT), which removes the instruction and its corresponding mapping to the response from instruction tuning. Instead, it focuses solely on establishing a response distribution. Our experiments demonstrate that RT models, trained only on responses, can effectively respond to a wide range of instructions akin to their instruction-tuned counterparts. In addition, we observe that the models can recognize and reject unsafe queries after learning a safety policy only from the response data. Furthermore, we find that these observations extend to an in-context learning setting. These findings support our hypothesis, highlighting the extensive inherent capabilities of pre-trained LLMs.
@inproceedings{an-etal-2025-revealing,title={Revealing the Inherent Instructability of Pre-Trained Language Models},author={An, Seokhyun and Kim, Minji and Kim, Hyounghun},editor={Christodoulopoulos, Christos and Chakraborty, Tanmoy and Rose, Carolyn and Peng, Violet},booktitle={Findings of the Association for Computational Linguistics: EMNLP 2025},month=nov,year={2025},address={Suzhou, China},publisher={Association for Computational Linguistics},url={https://aclanthology.org/2025.findings-emnlp.285/},doi={10.18653/v1/2025.findings-emnlp.285},pages={5305--5336},isbn={979-8-89176-335-7},}
Enabling Chatbots with Eyes and Ears: An Immersive Multimodal Conversation System for Dynamic Interactions
Jihyoung Jang, Minwook Bae, Minji Kim, and 2 more authors
In Proceedings of the 63rd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers), 2025
As chatbots continue to evolve toward human-like, real-world, interactions, multimodality remains an active area of research and exploration. So far, efforts to integrate multimodality into chatbots have primarily focused on image-centric tasks, such as visual dialogue and image-based instructions, placing emphasis on the "eyes" of human perception while neglecting the "ears", namely auditory aspects. Moreover, these studies often center around static interactions that focus on discussing the modality rather than naturally incorporating it into the conversation, which limits the richness of simultaneous, dynamic engagement. Furthermore, while multimodality has been explored in multi-party and multi-session conversations, task-specific constraints have hindered its seamless integration into dynamic, natural conversations. To address these challenges, this study aims to equip chatbots with "eyes and ears" capable of more immersive interactions with humans. As part of this effort, we introduce a new multimodal conversation dataset, Multimodal Multi-Session Multi-Party Conversation (M^3C), and propose a novel multimodal conversation model featuring multimodal memory retrieval. Our model, trained on the M^3C, demonstrates the ability to seamlessly engage in long-term conversations with multiple speakers in complex, real-world-like settings, effectively processing visual and auditory inputs to understand and respond appropriately. Human evaluations highlight the model’s strong performance in maintaining coherent and dynamic interactions, demonstrating its potential for advanced multimodal conversational agents.
@inproceedings{jang-etal-2025-enabling,title={Enabling Chatbots with Eyes and Ears: An Immersive Multimodal Conversation System for Dynamic Interactions},author={Jang, Jihyoung and Bae, Minwook and Kim, Minji and Hakkani-T{\"u}r, Dilek and Kim, Hyounghun},editor={Che, Wanxiang and Nabende, Joyce and Shutova, Ekaterina and Pilehvar, Mohammad Taher},booktitle={Proceedings of the 63rd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers)},month=jul,year={2025},address={Vienna, Austria},publisher={Association for Computational Linguistics},url={https://aclanthology.org/2025.acl-long.1519/},doi={10.18653/v1/2025.acl-long.1519},pages={31481--31512},isbn={979-8-89176-251-0},}
If you have any questions, please contact me at mzkim@postech.ac.kr.